AI-search performance is increasingly being discussed in terms of ROI. But before a visibility gain, citation increase, traffic change, or business result deserves that label, it needs to pass two different tests: How close is the measured outcome to actual business value, and how convincingly can that outcome be attributed to the intervention?
It is easy to collapse those questions into one. A company improves its visibility in AI-generated answers. Citations increase. Perhaps traffic changes. Somewhere along the way, someone calls the result ROI.
But each step represents a different outcome, and evidence that is strong at one stage does not automatically prove what happened at another. There is another problem: even when the measured outcome is economically meaningful, observing it does not necessarily establish what caused it.
That gives us two independent dimensions for judging an AI-search ROI claim:
- Business relevance: How close is the measured outcome to actual economic return?
- Causal strength: How convincingly does the evidence show that the intervention produced that outcome?
A credible AI-search ROI claim needs to survive both tests.
Test 1: What was actually measured?
It is useful to distinguish among retrieval, brand mention, citation, referral, business outcome, and incremental return. These should not be treated as a universal architecture describing how every AI system works. Nor should they be treated as an automatic funnel in which success at one stage guarantees success at the next. They are better understood as separate measurement questions:
- Was the content retrieved?
- Was the brand mentioned?
- Was a source cited?
- Did someone visit the site?
- Did that activity contribute to a business result?
- And finally: did the intervention produce enough incremental economic value to justify its cost?
The farther we move toward that final question, the closer we get to ROI. The problem arises when evidence from an upstream stage is used to support a downstream claim.
A citation increase is evidence about citations. By itself, it does not establish referrals, leads, sales, or return on investment. That distinction matters because controlled research has shown that techniques can affect measured AI visibility while leaving downstream business consequences unresolved.
In the SAGEO Arena benchmark, for example, changes intended to improve AI-answer visibility sometimes made documents less likely to reach the answer stage. The finding helps demonstrate why retrieval, reranking, and citation should be measured separately. But the benchmark does not establish what the same changes would do in production systems such as Google, ChatGPT, or Perplexity.
Similarly, an academic review of generative-engine optimization research concluded that controlled citation gains do not establish durable organic discovery or traffic gains.
These findings do not mean visibility is unimportant. They mean the claim should stop where the evidence stops.
Test 2: How do we know what caused the result?
The second test is separate from the first. Suppose a measured outcome is commercially interesting. That still leaves another question: What evidence shows that the intervention caused it?
Consider two findings about clicking.
A Pew Research Center observational study found that people in its sample clicked traditional links less often when an AI summary appeared. That is an important observed pattern, but differences in query mix and summary eligibility mean the comparison alone does not establish causation.
A separate desktop extension experiment by Agarwal and Sen found that AI Overviews causally reduced outbound organic clicks for eligible searches under the conditions tested.
The two findings concern a similar outcome—clicking—but they support different levels of inference. The observational result identifies an association. The experiment supports a causal conclusion within its tested setup. Neither one, however, establishes the incremental ROI of an AI-search optimization program.
That illustrates why causal strength and business relevance cannot be collapsed into the same scale. An experiment may provide strong causal evidence about an outcome that remains far upstream from revenue. A business observation may involve a more commercially relevant outcome while offering much weaker evidence about what caused it.
Strong causality does not make an upstream result ROI
This is one of the easiest distinctions to miss. Controlled evidence is valuable because it can strengthen attribution. But stronger attribution does not move the measured outcome farther downstream.
If an experiment establishes that an intervention changed source visibility, then there may be strong evidence for a visibility effect. That does not turn the effect into a traffic result. It does not turn it into a lead. And it does not turn it into ROI.
The endpoint still matters. Experimental control answers one question: Did the intervention cause the measured effect under these conditions? It does not automatically answer another: Did that effect create economic value?
This is why the two tests need to remain independent.
Business relevance does not make an observation causal
The reverse mistake is equally important. Evidence collected from a live website can feel more commercially meaningful than a controlled benchmark because it occurred in a real operating environment. But real-world relevance does not eliminate attribution problems.
Waikay's EntityMap case study, for example, reported an increase and redistribution in citations following installation of a structured entity file on one site. The pattern was consistent with the EntityMap hypothesis.
But it was a single-site before-and-after observation without a control. The aggregate change was also heavily influenced by multilingual pages, and other confounding factors could not be ruled out.
That does not make the observation useless. It changes the strength of the claim we can responsibly make from it. The case can support further investigation of the hypothesis. It cannot, by itself, establish that the intervention caused the observed citation changes.
Again, business relevance and causal strength are doing different jobs.
Think of AI-search evidence on two axes
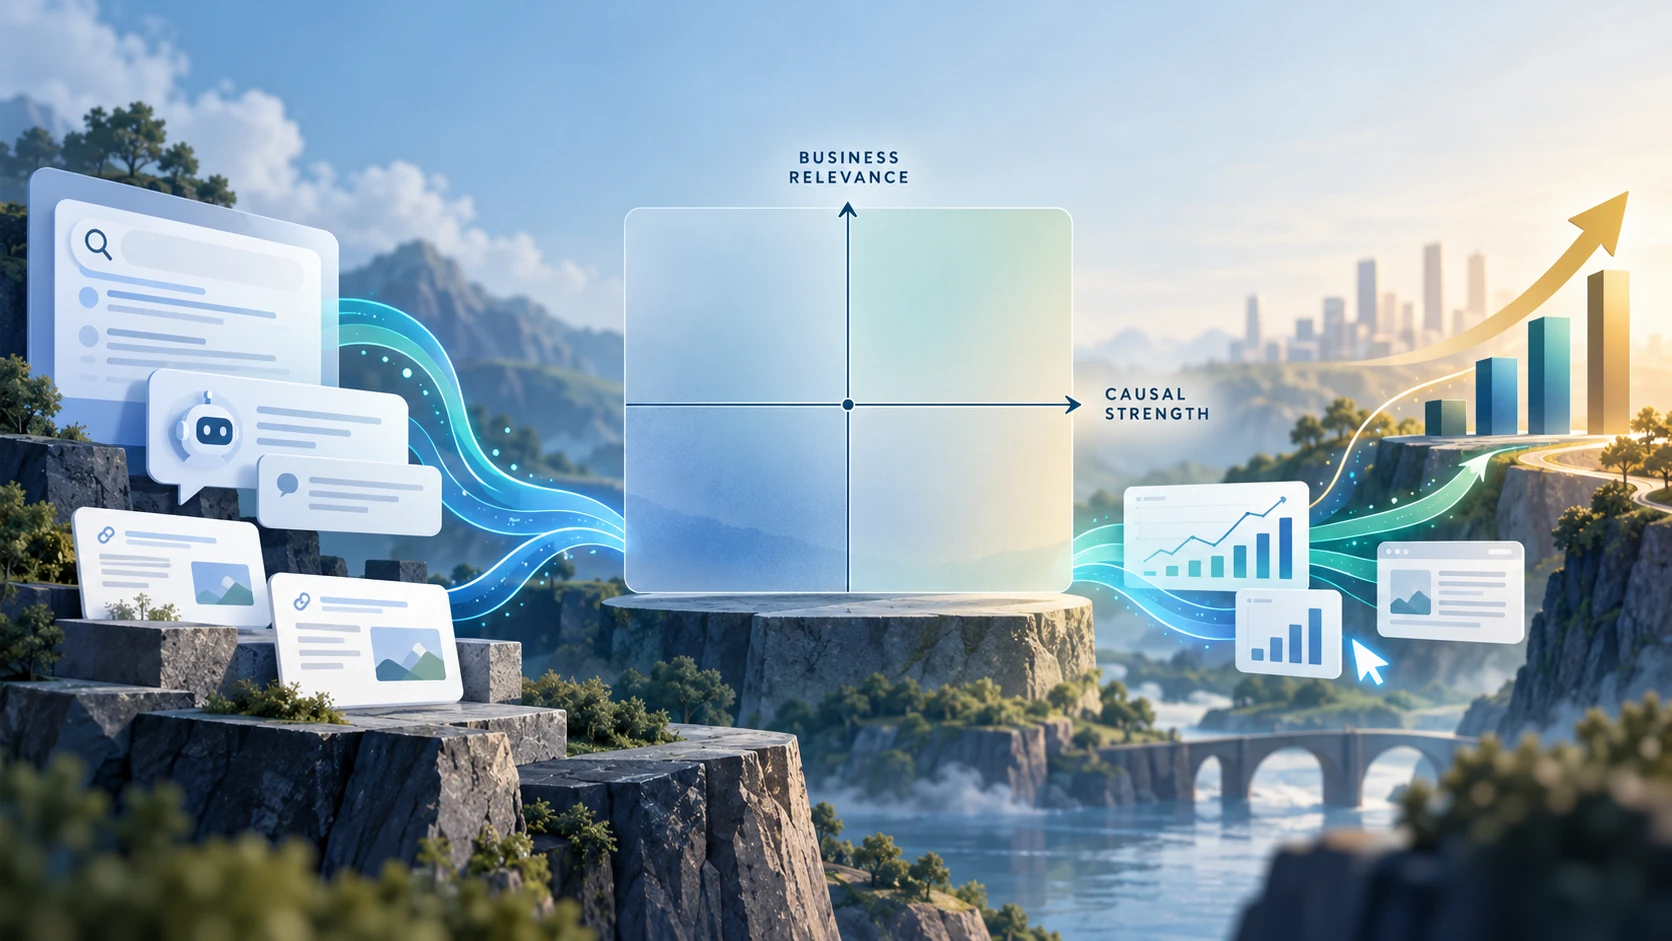
Instead of ranking AI-search evidence on a single ladder, it may be more useful to picture a matrix. One axis asks how close the measured outcome is to economic value. The other asks how strong the attribution evidence is.
An upstream result with strong experimental attribution can occupy one part of that matrix. A commercially important observation with weak causal attribution can occupy another. The strongest basis for an ROI claim would need to move in both directions: toward a meaningful business outcome and toward credible evidence that the intervention caused the incremental result.
The research assembled here does not complete that journey. It contains evidence about visibility, citations, clicking, experimental effects, observational patterns, and the limitations of translating controlled gains into durable discovery or traffic.
What it does not contain is an end-to-end causal demonstration that an AI-search optimization intervention produced incremental leads, sales, or economic return.
That absence is not a footnote. It is the central measurement issue.
Missing evidence is part of the conclusion
AI-search measurement becomes misleading when unanswered questions quietly turn into assumed connections:
- Retrieval does not automatically imply mention.
- Mention does not automatically imply citation.
- Citation does not automatically imply referral.
- Referral does not automatically imply a business outcome.
- A business outcome observed after an intervention does not automatically establish that the intervention caused it.
Those are not arguments against measuring upstream outcomes. They are arguments for labeling them accurately.
Visibility can be useful. Citations can be useful. Referral traffic can be useful. Each tells us something different. The problem begins when one is presented as proof of another without evidence connecting the two.
A practical audit for the next AI-search ROI claim
Before accepting an AI-search result as evidence of ROI, ask:
- What exactly was measured? Was the result about retrieval, a brand mention, citation, referral, a business outcome, or actual incremental return?
- How close is that outcome to economic value? Is the result itself a business outcome, or is downstream value being inferred?
- What supports the causal claim? Was there a controlled comparison, an observational relationship, or simply a before-and-after change?
- Could other factors explain the result? A live-site result can be commercially relevant while still leaving attribution uncertain.
- Does the evidence apply outside the tested setting? Controlled benchmarks can establish effects within their conditions without proving universal production effects.
- Were downstream outcomes actually observed? Do not substitute citations or visibility for referrals, leads, sales, or other business results.
- Were costs and incrementality established? A financial return requires more than showing that a metric improved after work was performed.
The practical standard is simple:
An AI-search ROI claim should extend no further than both its measured business relevance and its attribution evidence allow.
That standard does not diminish AI-search visibility. It gives us a more rigorous way to understand what the evidence actually says—and what it does not yet say.
Sources
- Agarwal and Sen (2026). The Impact of Google AI Overviews on Publisher Traffic. SSRN.
papers.ssrn.com/sol3/papers.cfm?abstract_id=6513059 (opens in a new tab) - Pew Research Center (July 22, 2025). Google users are less likely to click on links when an AI summary appears in the results.
pewresearch.org/short-reads/2025/07/22/google-users-are-less-likely-to-click-on-links-when-an-ai-summary-appears-in-the-results/ (opens in a new tab) - Waikay / EntityMap (June 17, 2026). EntityMap Bing case study — citation redistribution after structured entity file.
waikay.io/entitymap-bing-case-study/ (opens in a new tab) - Kim, Jeong, Kim, Lee and Lee (February 2026). SAGEO Arena.
arxiv.org/abs/2602.12187 (opens in a new tab)
DOI: 10.1145/3770855.3818146 (opens in a new tab) - Martinez (July 2026). Optimizing Visibility in Generative Engines.
arxiv.org/abs/2607.14035 (opens in a new tab)